 Tech Tribers
System Design: Designing a Rate Limiter
A practical walk through rate-limiter design: what you are actually protecting, token bucket versus sliding window, a Java sketch, and how to make it correct across many servers.
3 min read
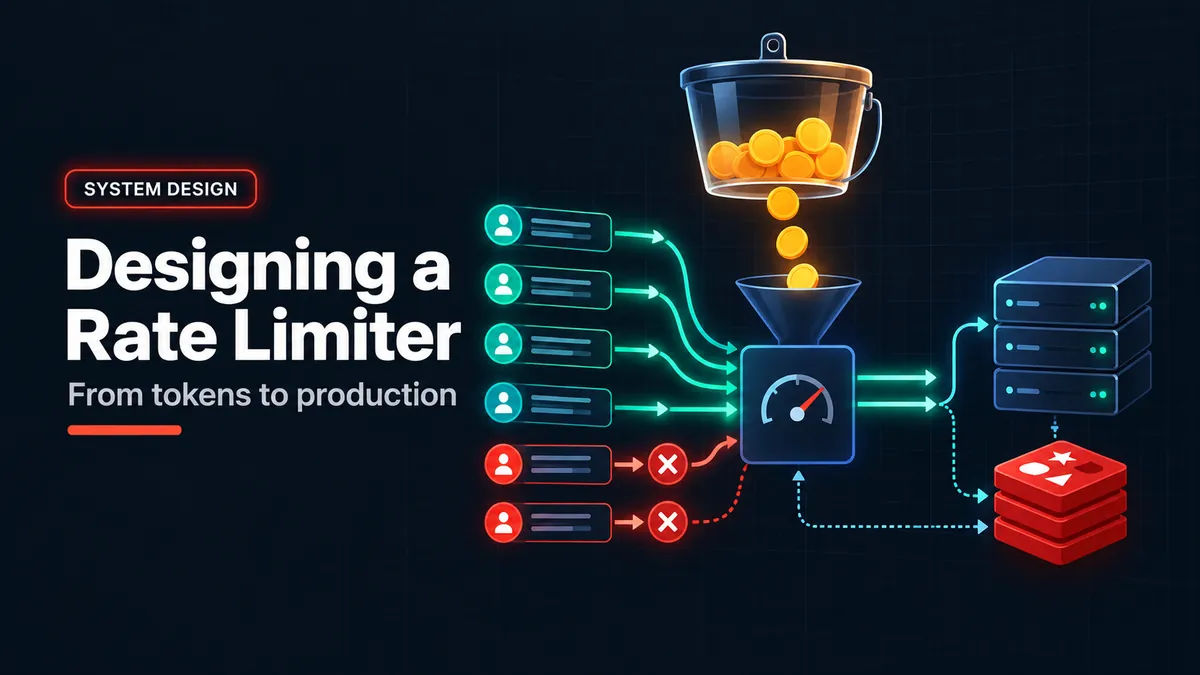
Every public API eventually needs a rate limiter: the component that decides whether a caller has asked for too much, too fast. Get it wrong and you either let one client melt your backend or you throttle honest traffic and generate support tickets. Here is how to reason about the design.
Start with the goal, not the algorithm
A rate limiter protects three different things, and which one you care about shapes the design:
- Fairness so no single tenant starves the others.
- Cost control to cap calls to an expensive downstream or a metered third-party API.
- Abuse prevention to blunt credential-stuffing and scraping.
Decide the limit's dimension too: per API key, per IP, or per user. Most real systems layer several of these at once.
Pick an algorithm
Two designs cover the large majority of cases:
- Token bucket - a bucket refills at a steady rate up to a cap, and each request spends one token. It absorbs short bursts, which users love, while bounding the sustained rate. This is the sensible default.
- Sliding window - counts requests across a moving time window, which is more accurate at the boundary than a fixed window but costs more memory.
A fixed-window counter is the easiest to build but suffers the double-burst problem: a client can fire a full window of requests at 0:59 and again at 1:00.
A token bucket, sketched
class TokenBucket {
    private final long capacity;
    private final double refillPerSecond;
    private double tokens;
    private long lastRefillNanos;

    synchronized boolean tryAcquire() {
        refill();
        if (tokens >= 1) {
            tokens -= 1;
            return true;
        }
        return false;
    }

    private void refill() {
        long now = System.nanoTime();
        double elapsed = (now - lastRefillNanos) / 1_000_000_000.0;
        tokens = Math.min(capacity, tokens + elapsed * refillPerSecond);
        lastRefillNanos = now;
    }
}
Make it work across many servers
The in-memory bucket above breaks the moment you run more than one instance: each replica keeps its own count, so a limit of 100/s quietly becomes 100/s per node. Move the state into a shared store, usually Redis, and make the check-and-decrement atomic so two concurrent requests cannot both spend the last token. A small Lua script that reads the counter, tests it, and writes it back runs atomically on the Redis server:
# evaluate the limiter script: KEY, then limit and window-seconds as args
redis-cli --eval limiter.lua rate:key123 , 100 60
Tell the client what happened
- Return 429 Too Many Requests when the limit is exceeded.
- Send a
Retry-Afterheader so well-behaved clients back off instead of hammering. - Expose
X-RateLimit-LimitandX-RateLimit-Remainingso callers can self-throttle before they hit the wall.
Finally, decide up front whether the limiter fails open or closed: if Redis is unreachable, do you drop the limit or reject traffic? Either can be right, but silence is not a decision.